Run a Multi-turn LLM experiment
Train LLMPPO against a language-based gym. Multi-turn means advantage_granularity is turn (the default on a simulation environment). Token-level advantages are the other setting, used more often on reasoning tables.
Prerequisites
A validated language-based environment. It shows up as an RL Environment row in the wizard.
1. Open the project
On Experiments, open your Advanced Training project.
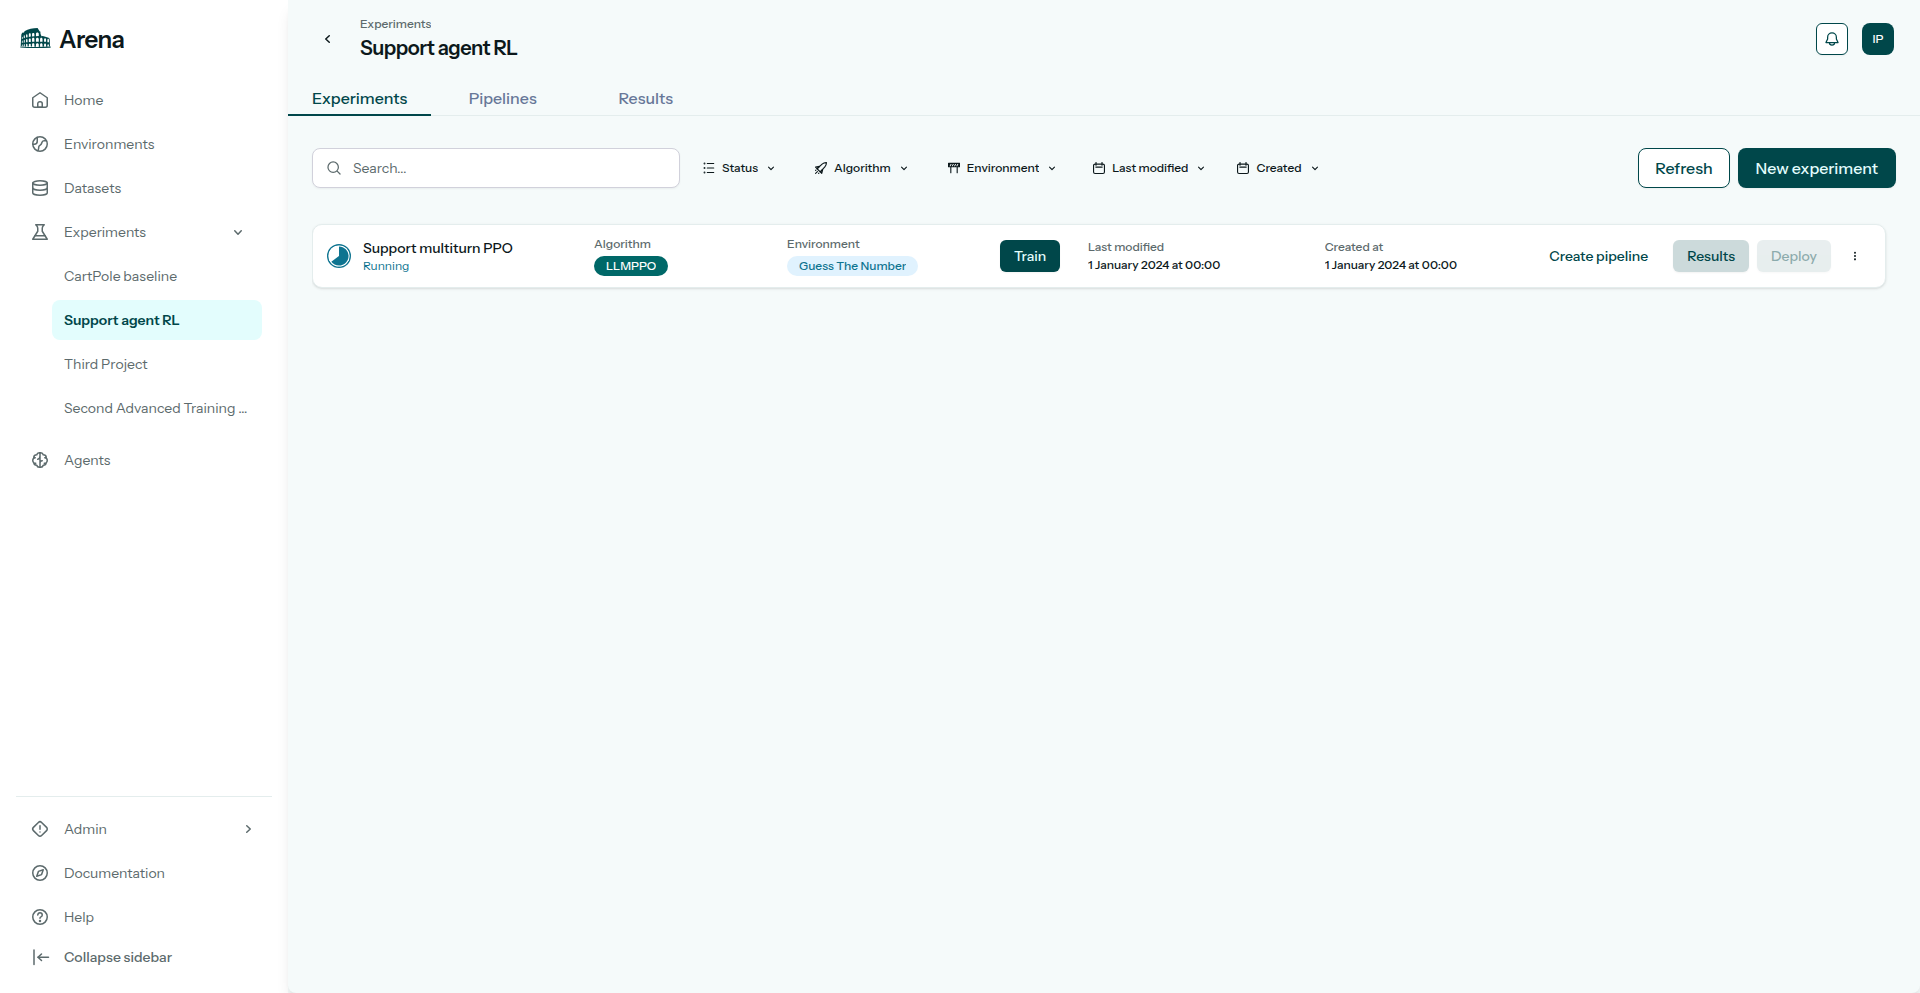
The Advanced Training project page.
2. New experiment
Click New experiment, name it, and save to open the wizard.
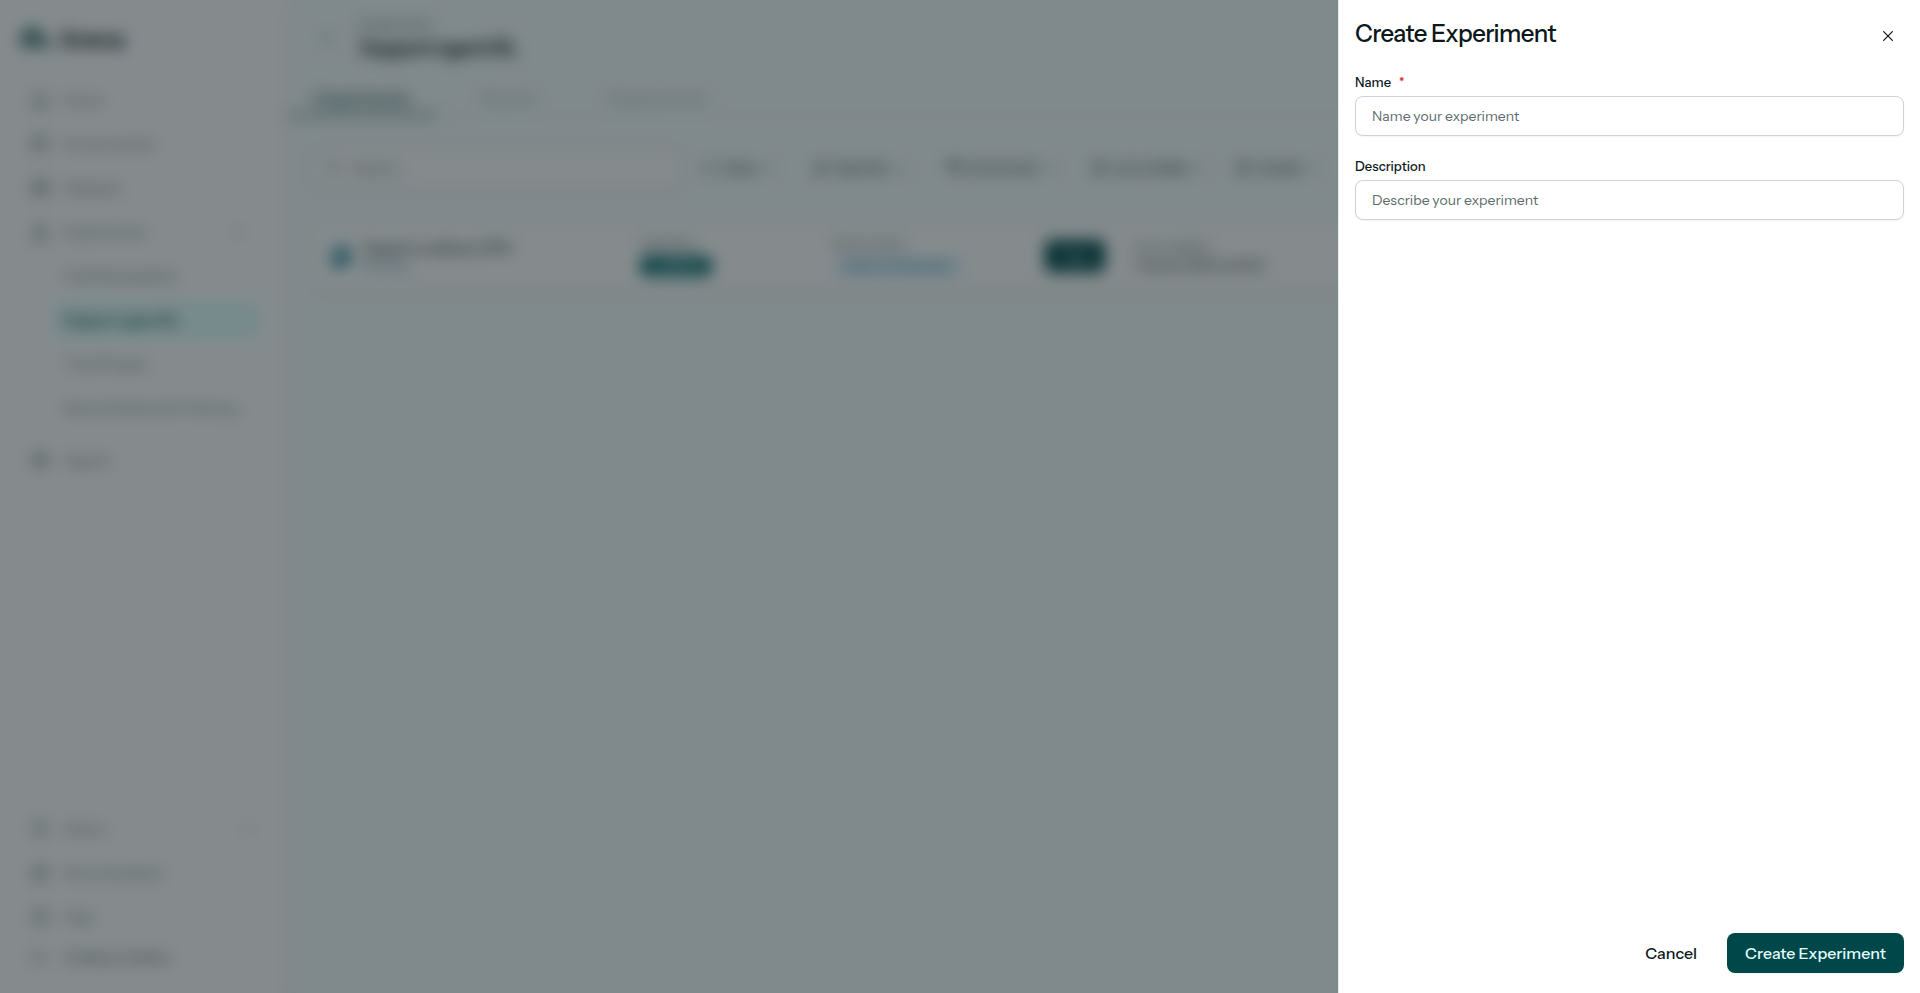
Creating a new experiment.
3. Environment step
On Environment, select the language-based gym (use Select version if the grid asks).
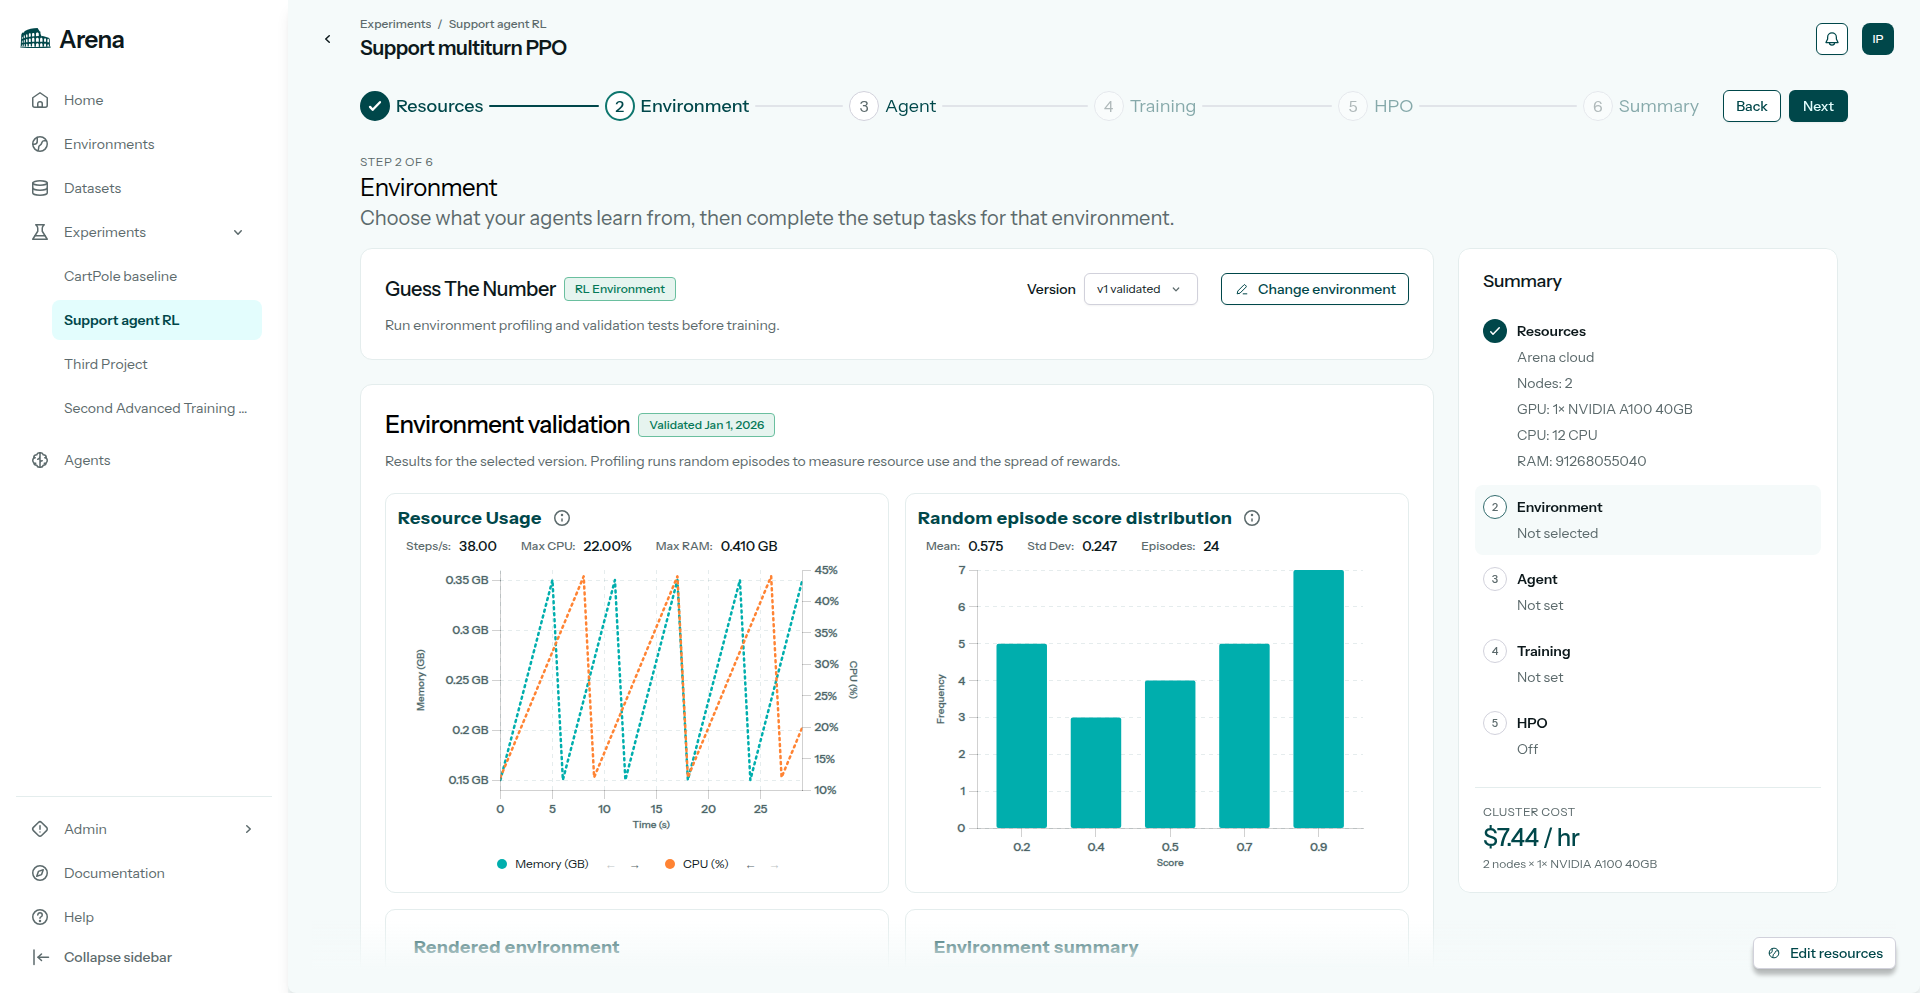
Selecting a language-based gym in the wizard.
4. Agent
The catalog algorithm is LLMPPO. On a language-based gym the Agent step labels it PPO. Select PPO, pick a pretrained model, and confirm advantage granularity is turn. Click Next.
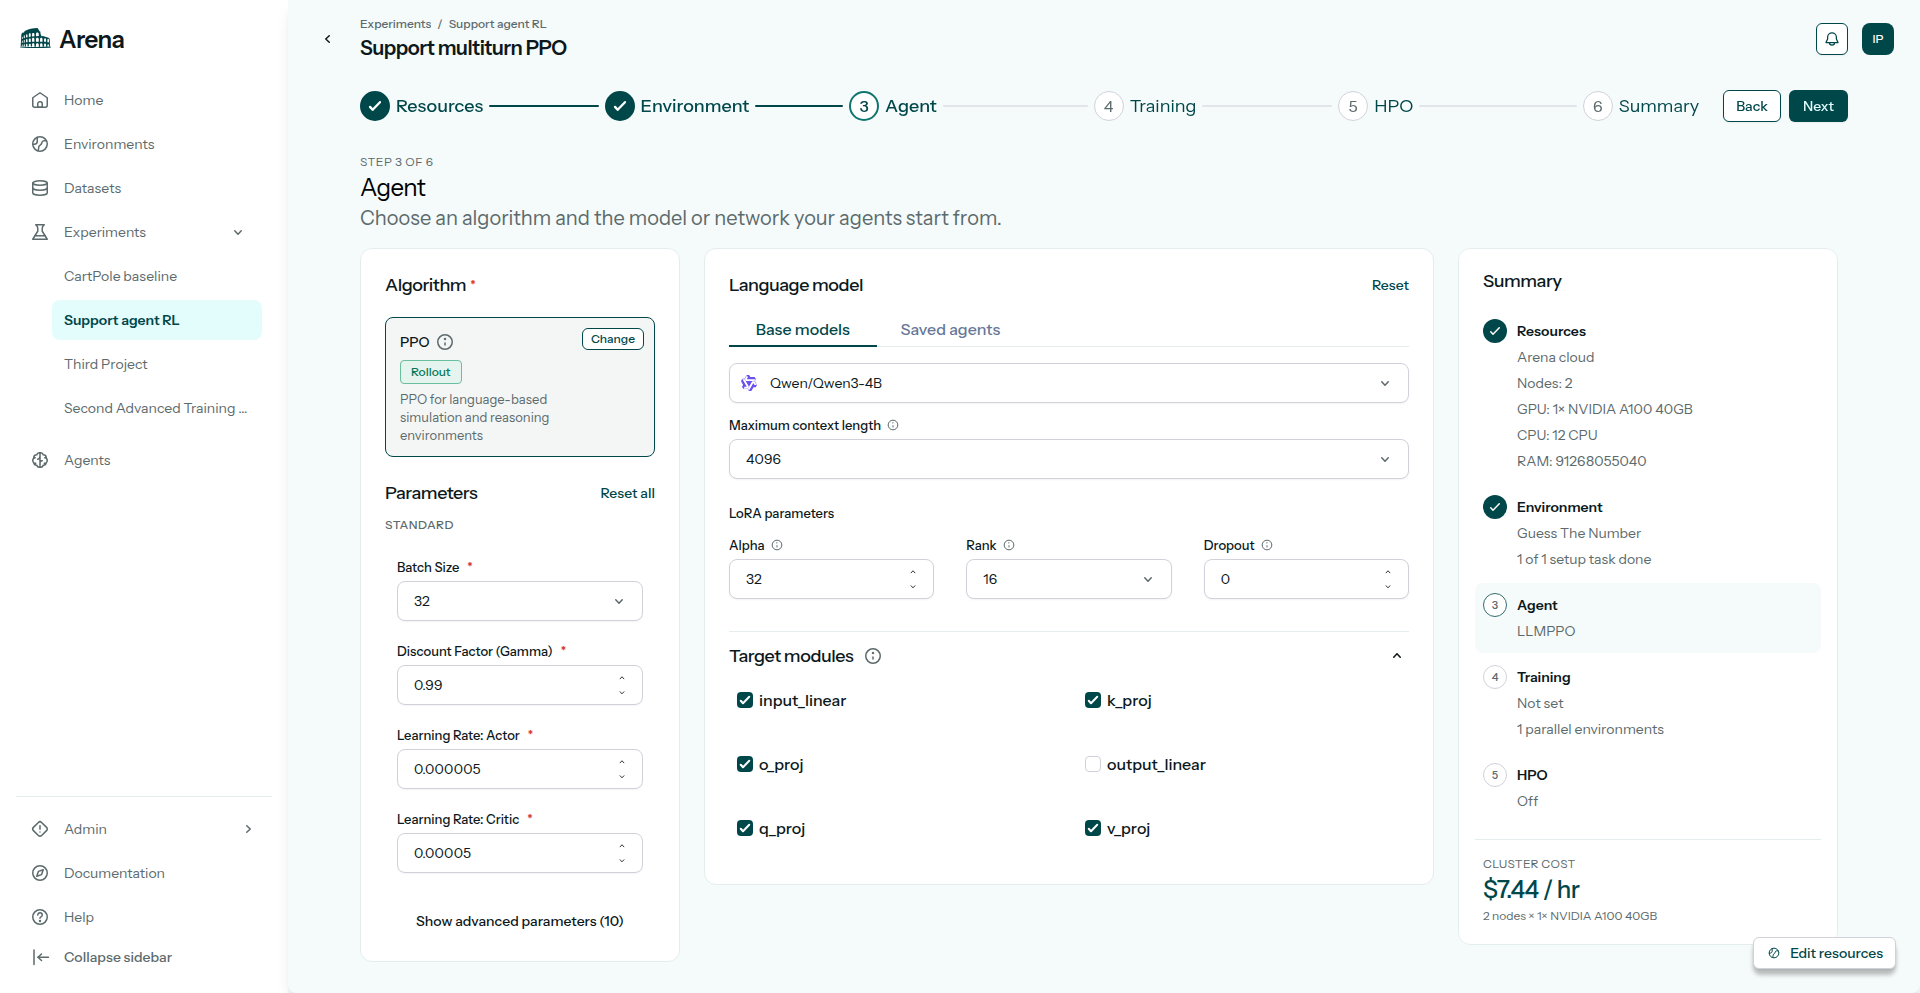
The Agent step with PPO.
5. Training
Set training steps and related options, then continue to HPO or Summary.
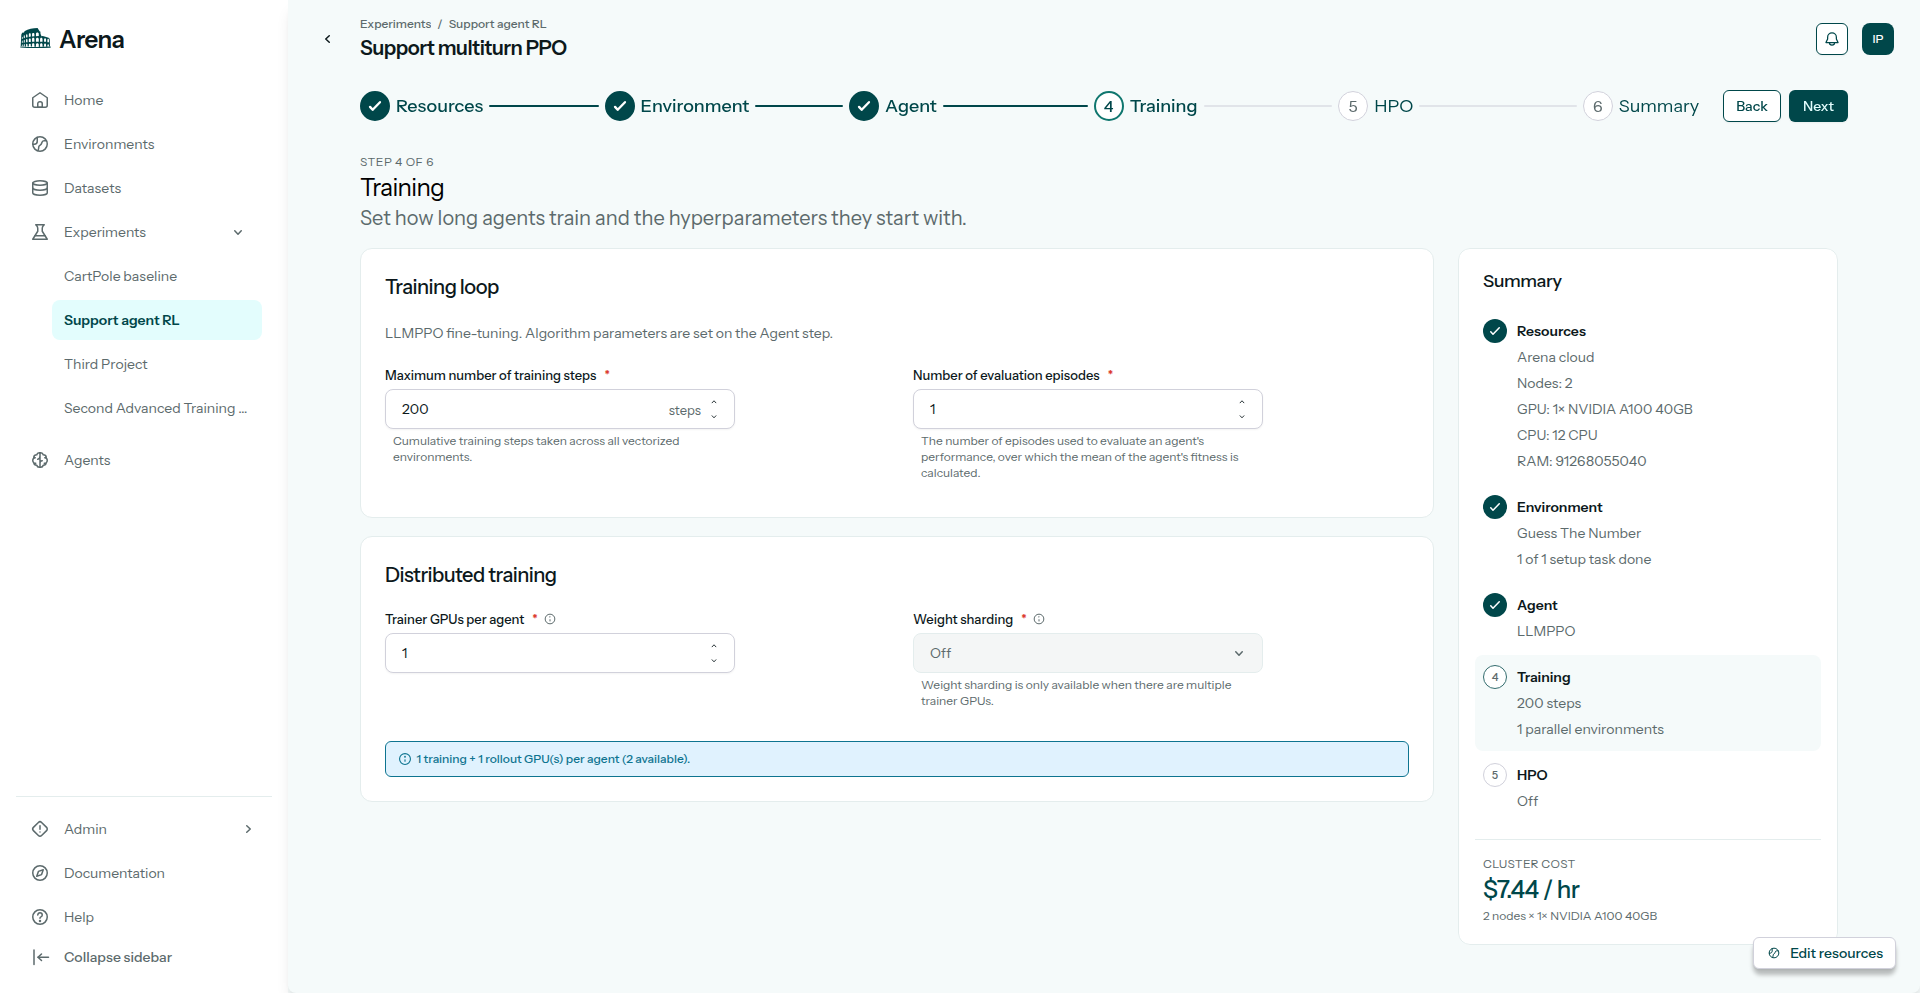
The Training step.
6. Summary
Review the configuration on Summary.
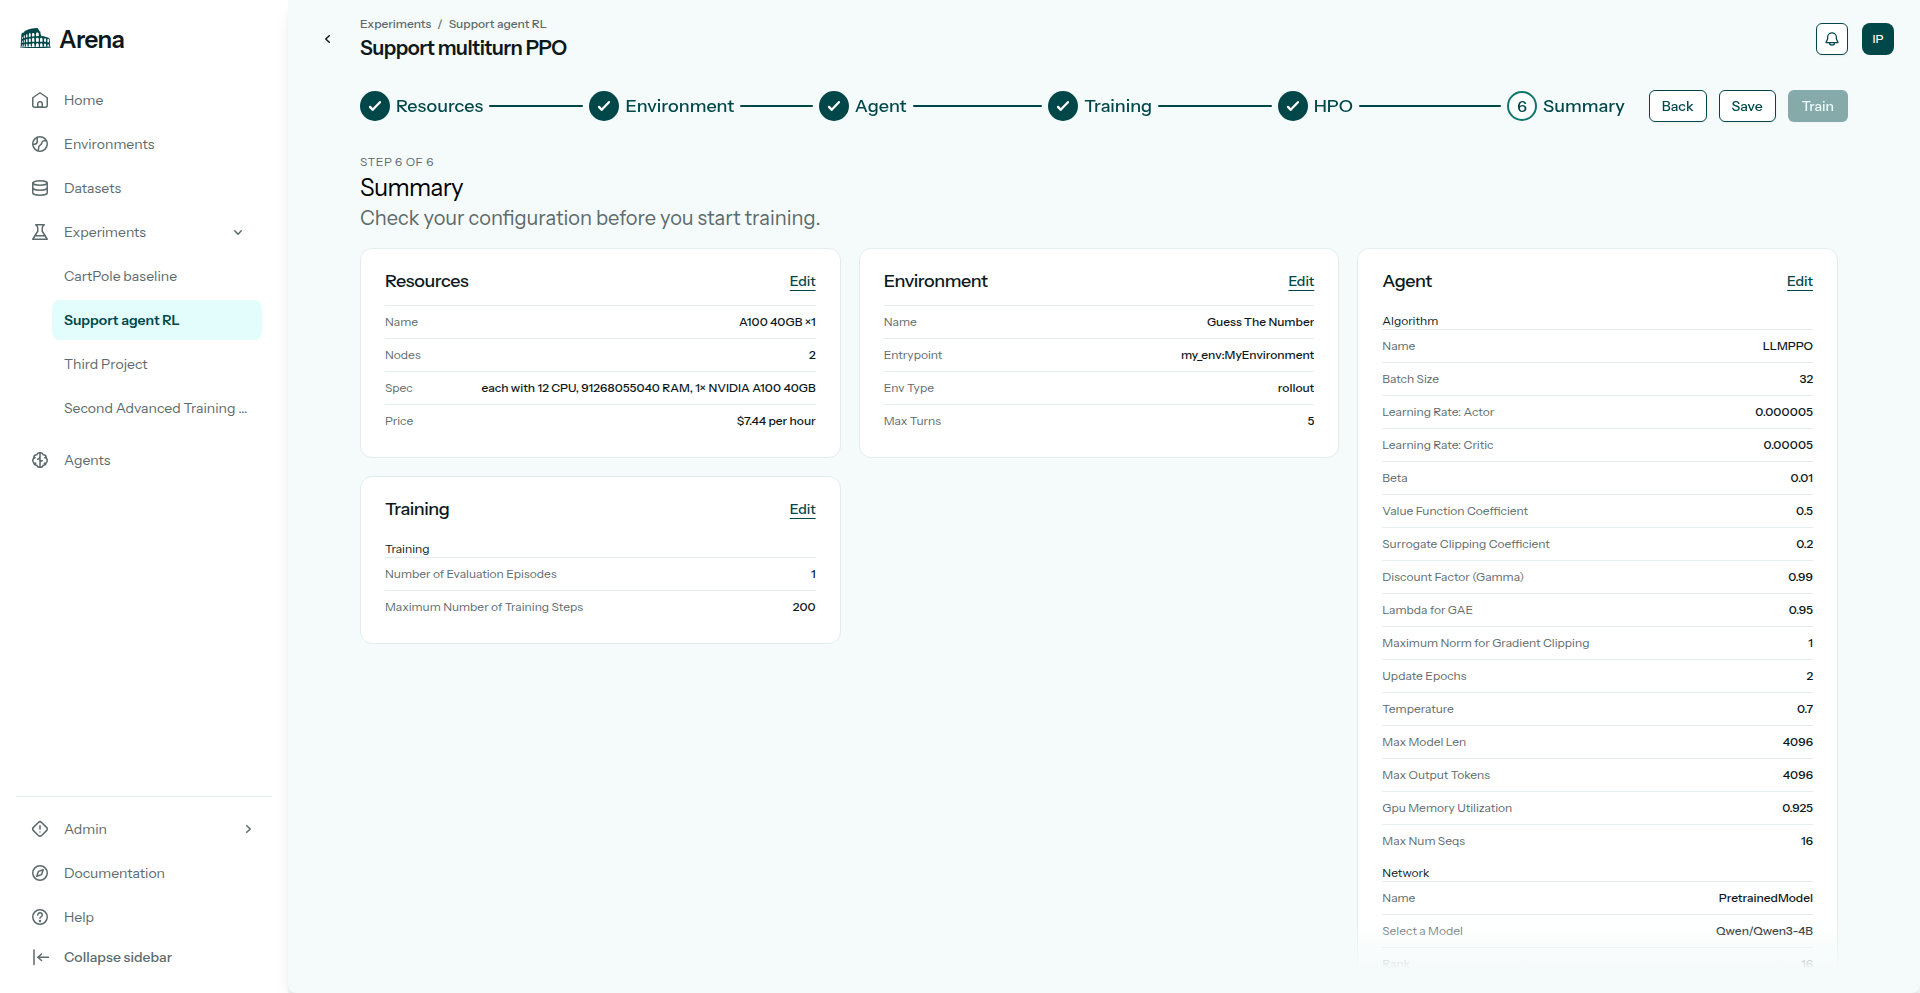
Summary before starting the run.
7. Running experiment
Click Train. The experiment row shows status while the job runs.
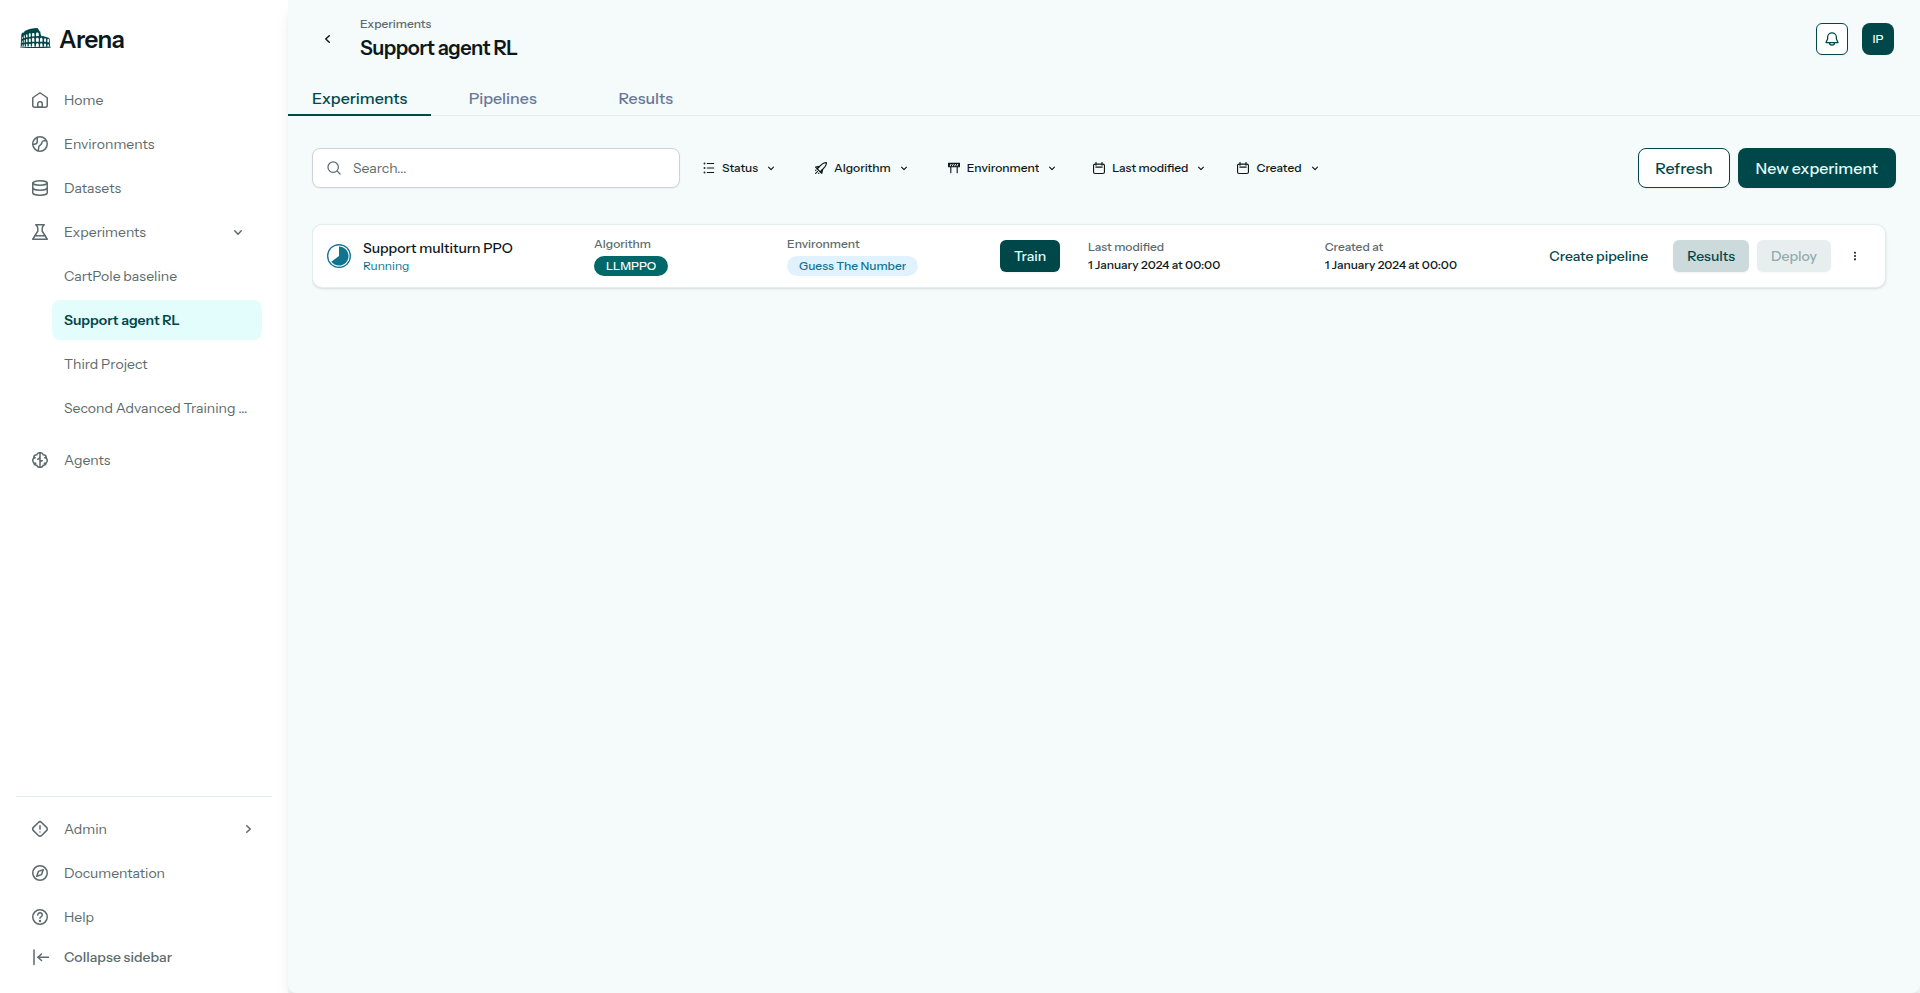
An experiment with an active training status.
From the terminal
Save a default spec from Python as run-spec.json, then submit. Copy a resource id from arena resources list. List gym entrypoints with arena env entrypoints ticket-sim --version v1.
Install the CLI and sign in (Authentication):
pip install "agilerl[arena]"
arena login
# or: export ARENA_API_KEY=arena_pat_…
import json
from pathlib import Path

from agilerl.arena import ArenaClient

with ArenaClient() as client:
    spec = client.get_default_run_spec(
        algorithm="LLMPPO",
        gym_env="ticket-sim",
    )
    spec["algorithm"]["advantage_granularity"] = "turn"
    Path("run-spec.json").write_text(json.dumps(spec, indent=2))
arena env entrypoints ticket-sim --version v1

arena resources list

arena experiments submit ./run-spec.json --project llm-work --experiment-name llmppo-run --resource-id a2-highgpu-1g --num-nodes 2
On a language gym the default spec already uses advantage_granularity turn.
Python
from agilerl.arena import ArenaClient

with ArenaClient() as client:
    spec = client.get_default_run_spec(
        algorithm="LLMPPO",
        gym_env="ticket-sim",
    )
    spec["algorithm"]["advantage_granularity"] = "turn"
    client.submit_experiment(
        manifest=spec,
        project="llm-work",
        resource_id="a2-highgpu-1g",
        experiment_name="llmppo-run",
        num_nodes=2,
    )
    print(client.list_experiments(project="llm-work"))