Run a Reasoning experiment
Train CISPO on a reasoning dataset in an Advanced Training project. CISPO sits in the same family as GRPO and GSPO: group-based updates with a more conservative policy step.
Prerequisites
Advanced Training project with a reasoning dataset (question / answer columns).
See Reasoning datasets if you still need to upload data.
1. Open the project
On Experiments, open your Advanced Training project.
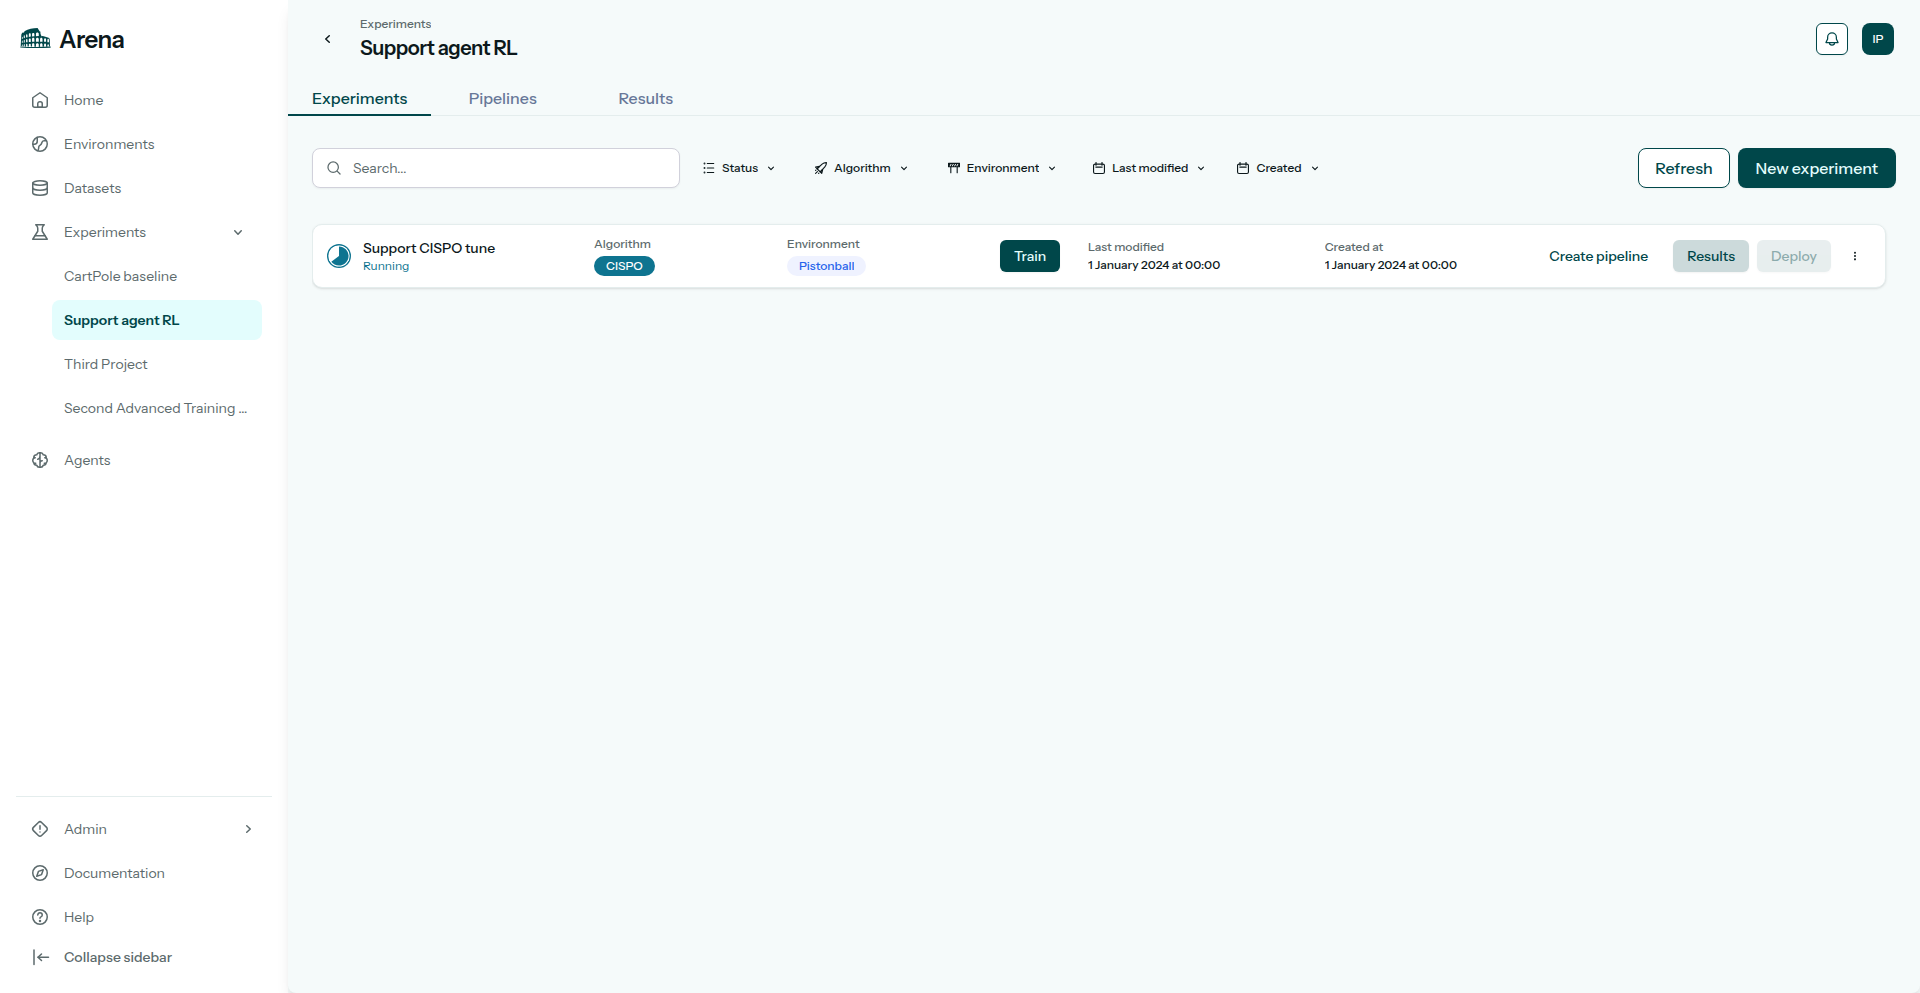
The Advanced Training project page.
2. New experiment
Click New experiment, name it, and save to open the wizard.
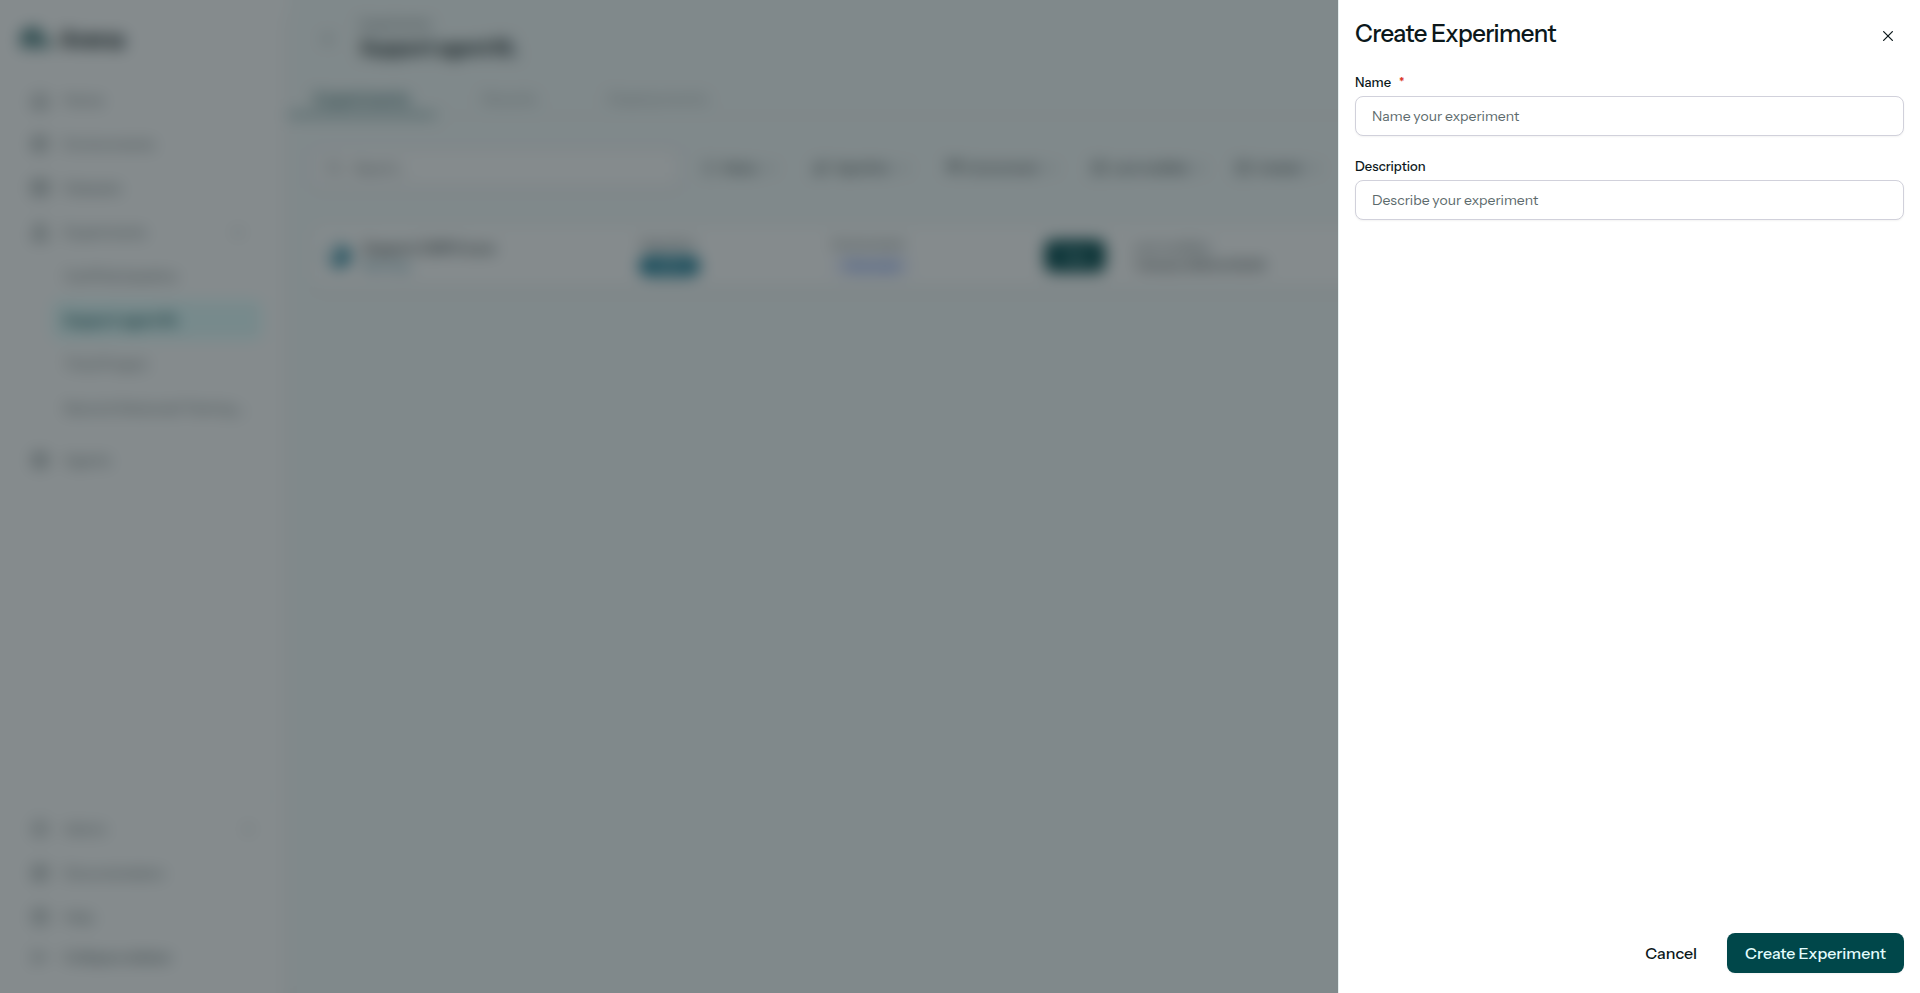
Creating a new experiment.
3. Environment step
On Environment, select your reasoning dataset. Complete Prompts: user prompt, Python f-string, and a rendered sample of Question / Answer.
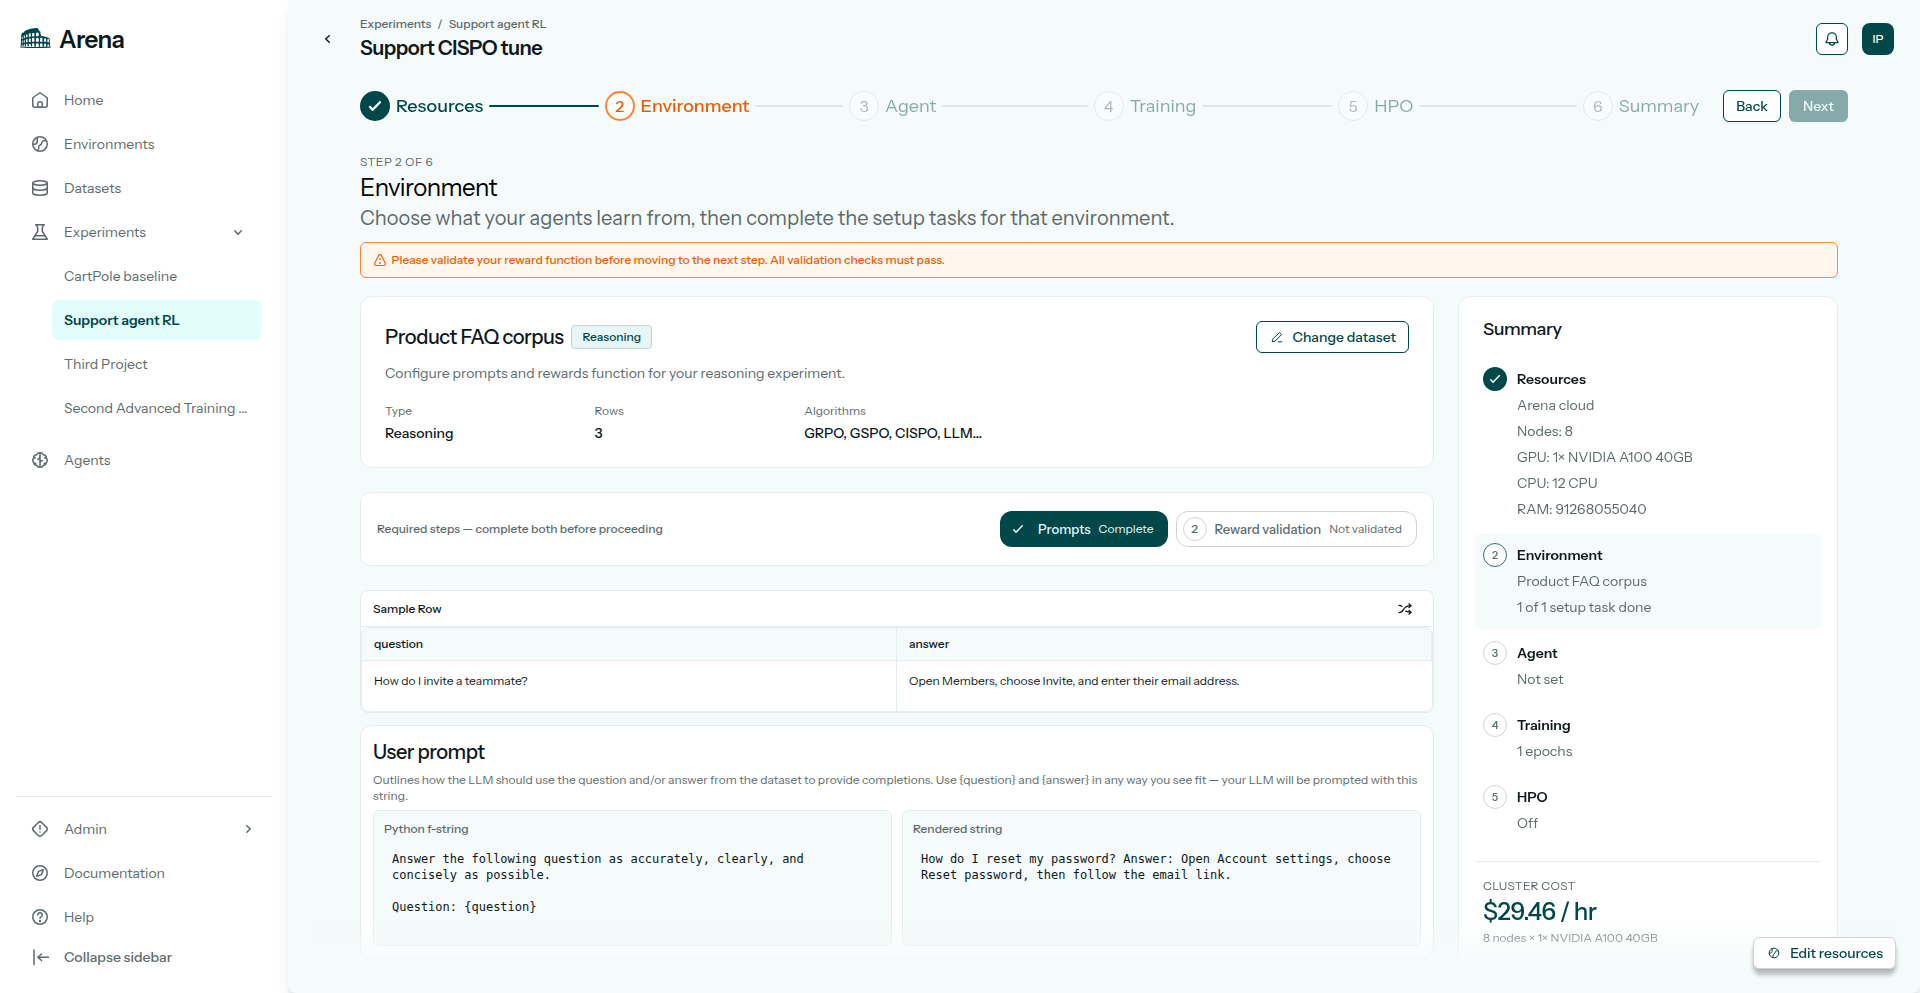
Selecting a reasoning dataset in the wizard.
4. Reward function
On Reward Function, edit reward.py and click Validate.
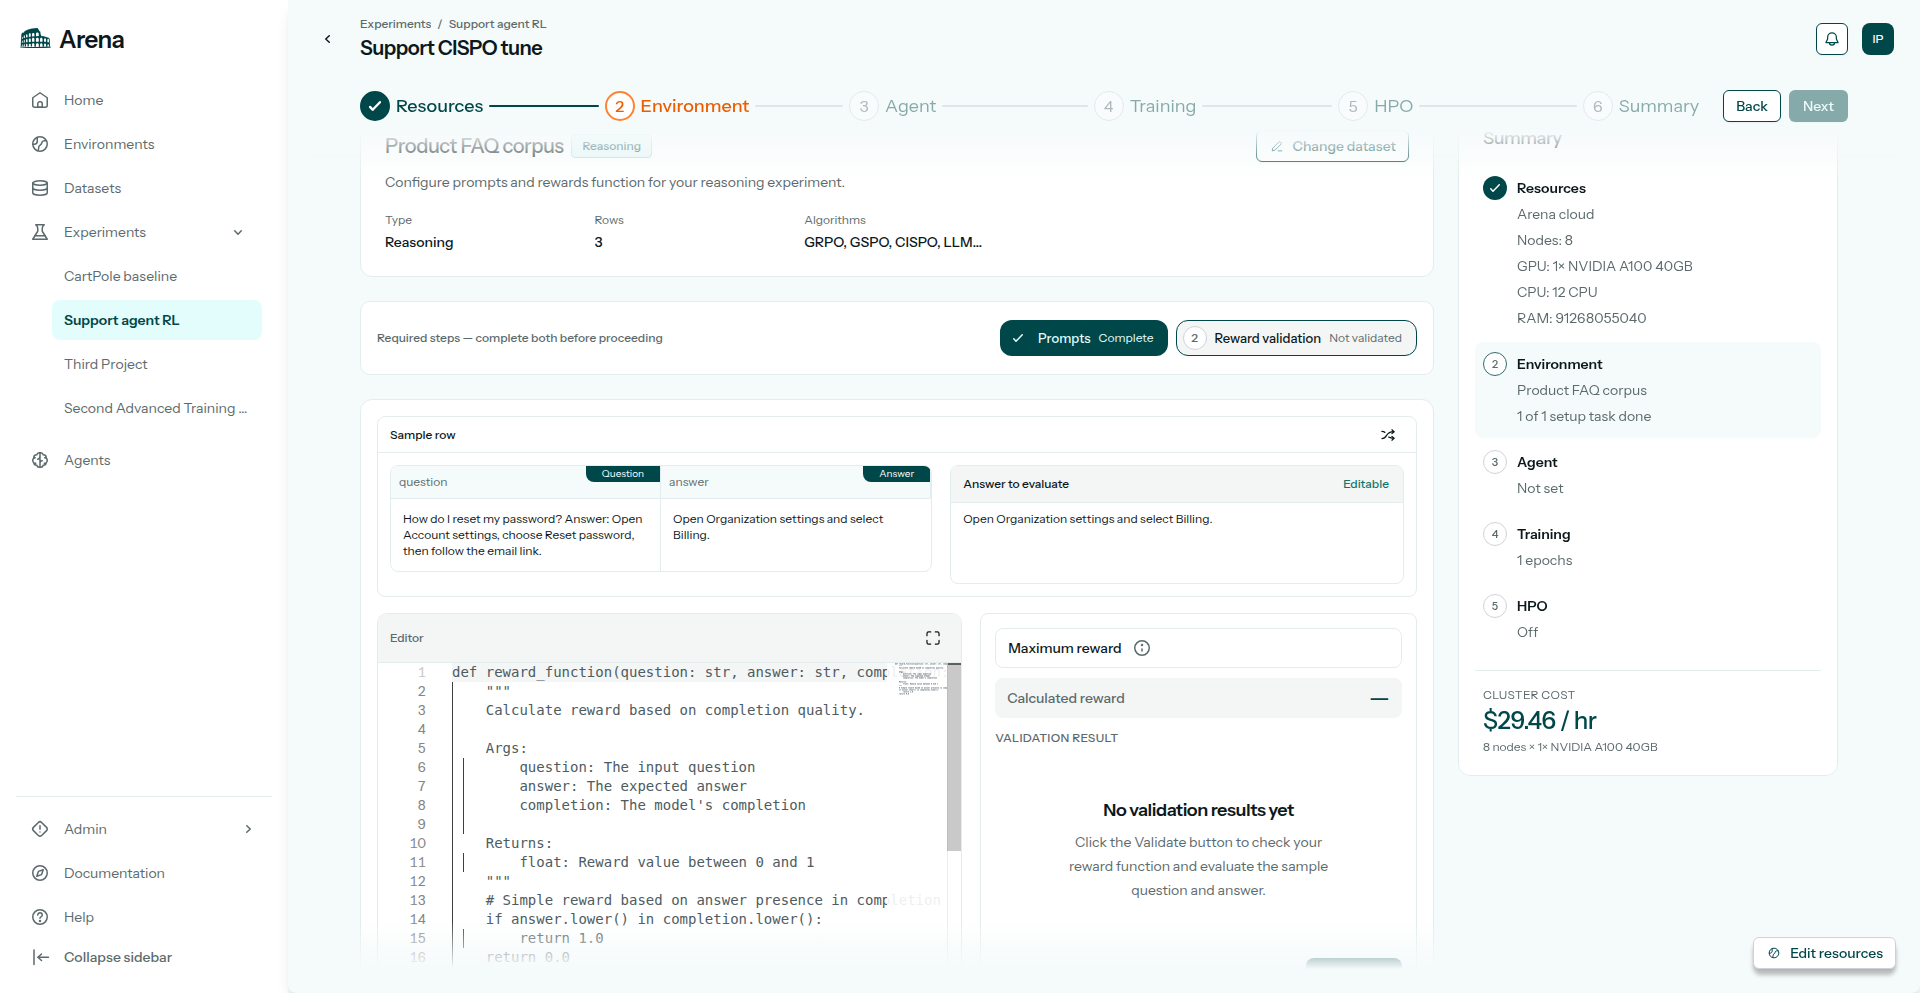
Writing the reward function.
5. Reward validation
Check the Validation tab for a passing result and a calculated reward. Next stays disabled until prompts and reward validation both succeed.
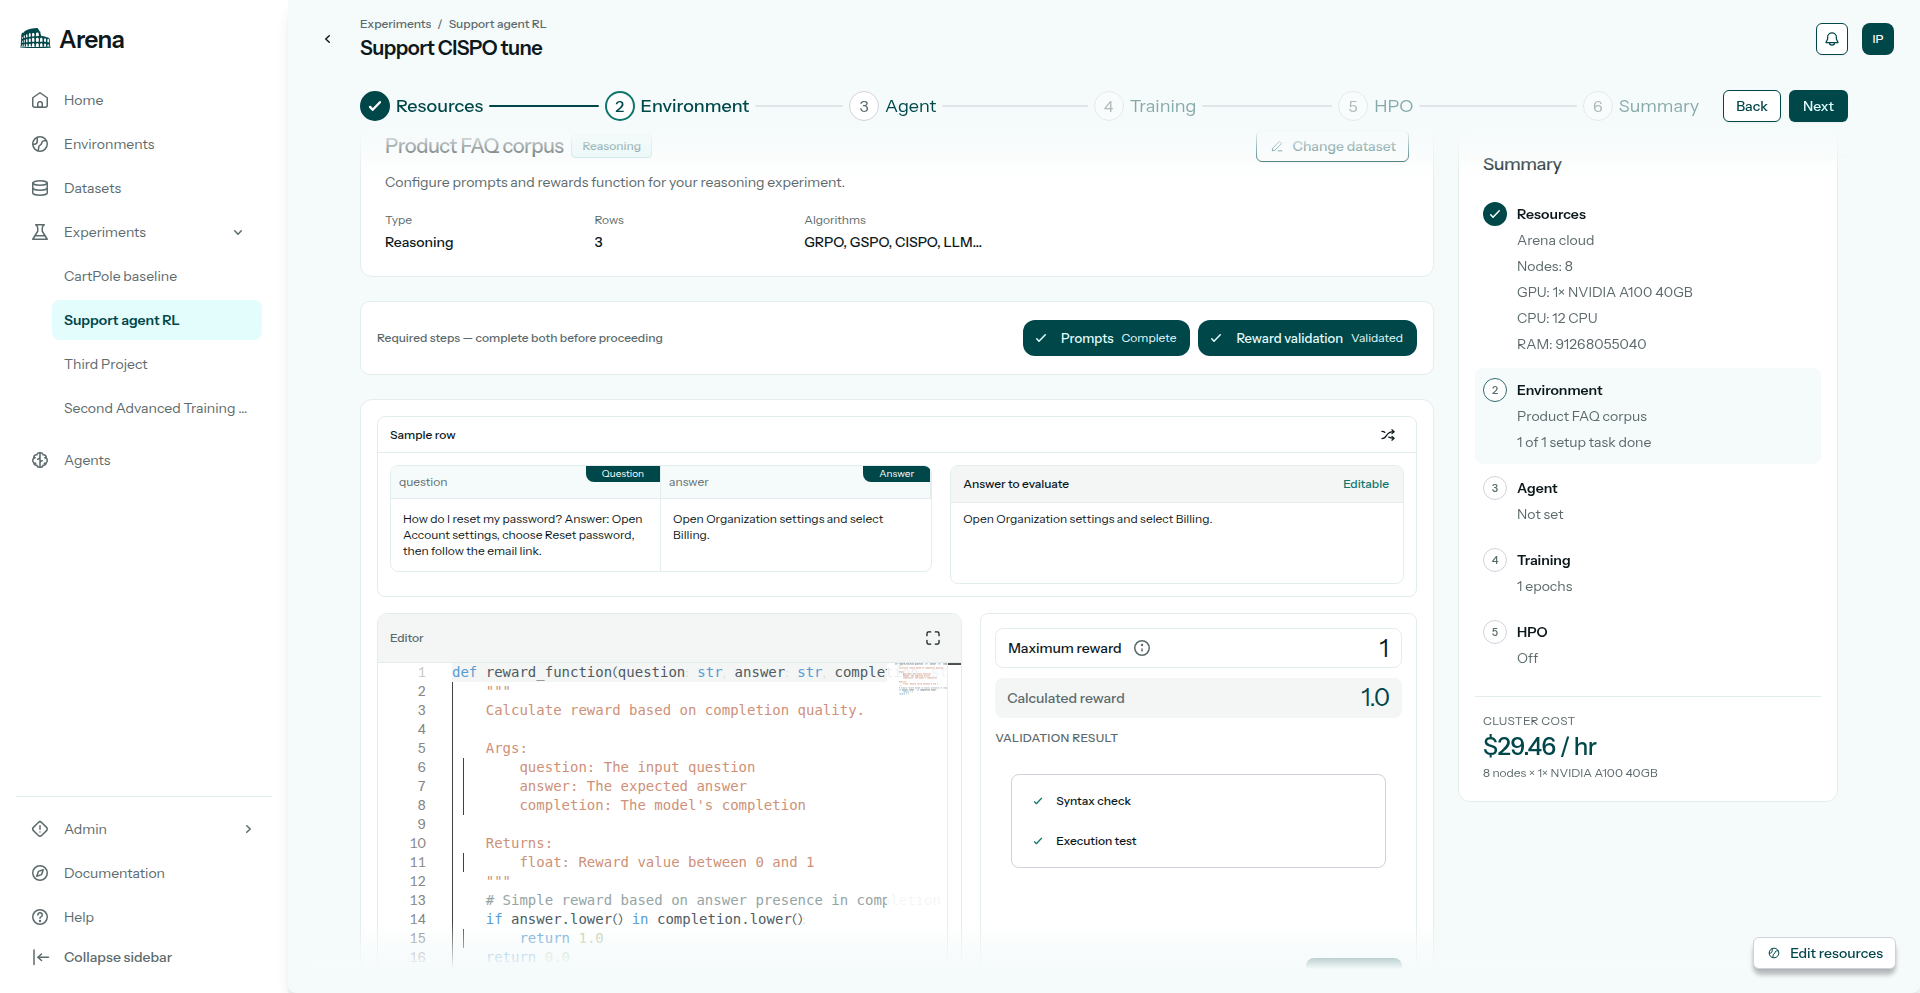
Validation results after Validate.
6. Agent
Choose CISPO and a pretrained model. Click Next.
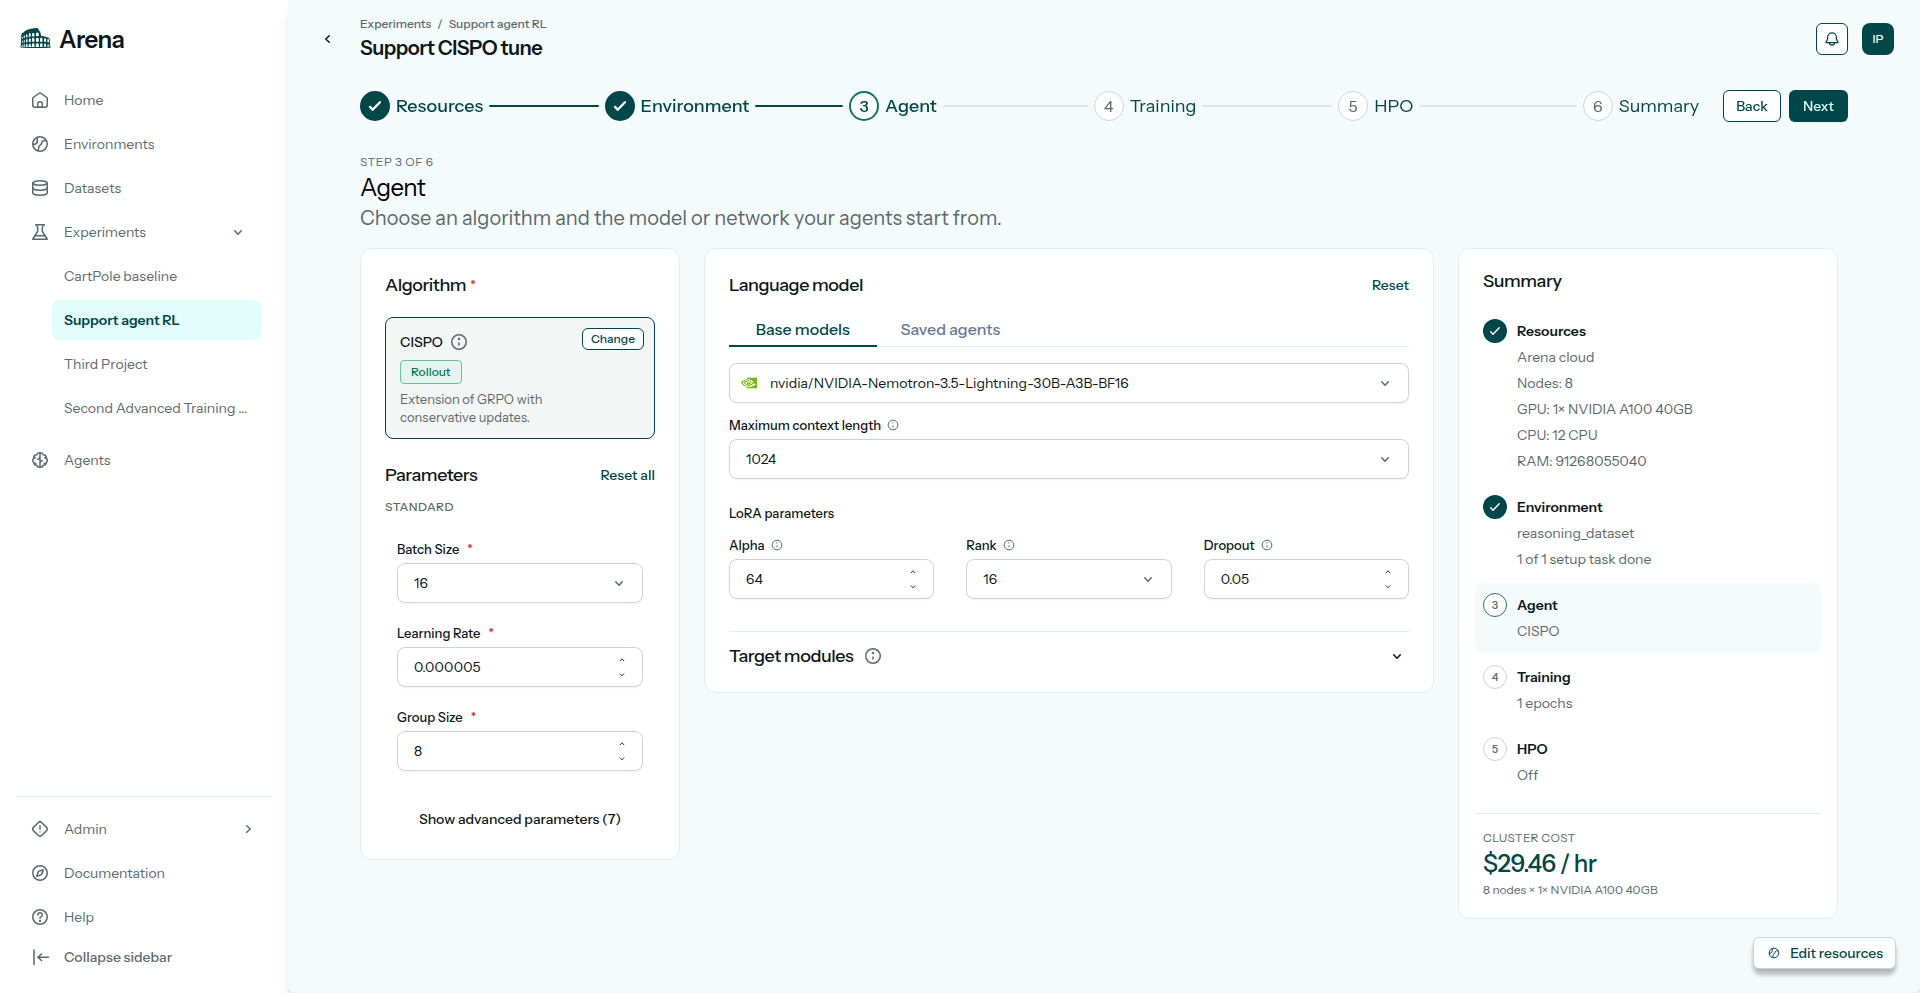
The Agent step with CISPO.
7. Training
Set training steps and related options, then continue to HPO or Summary.
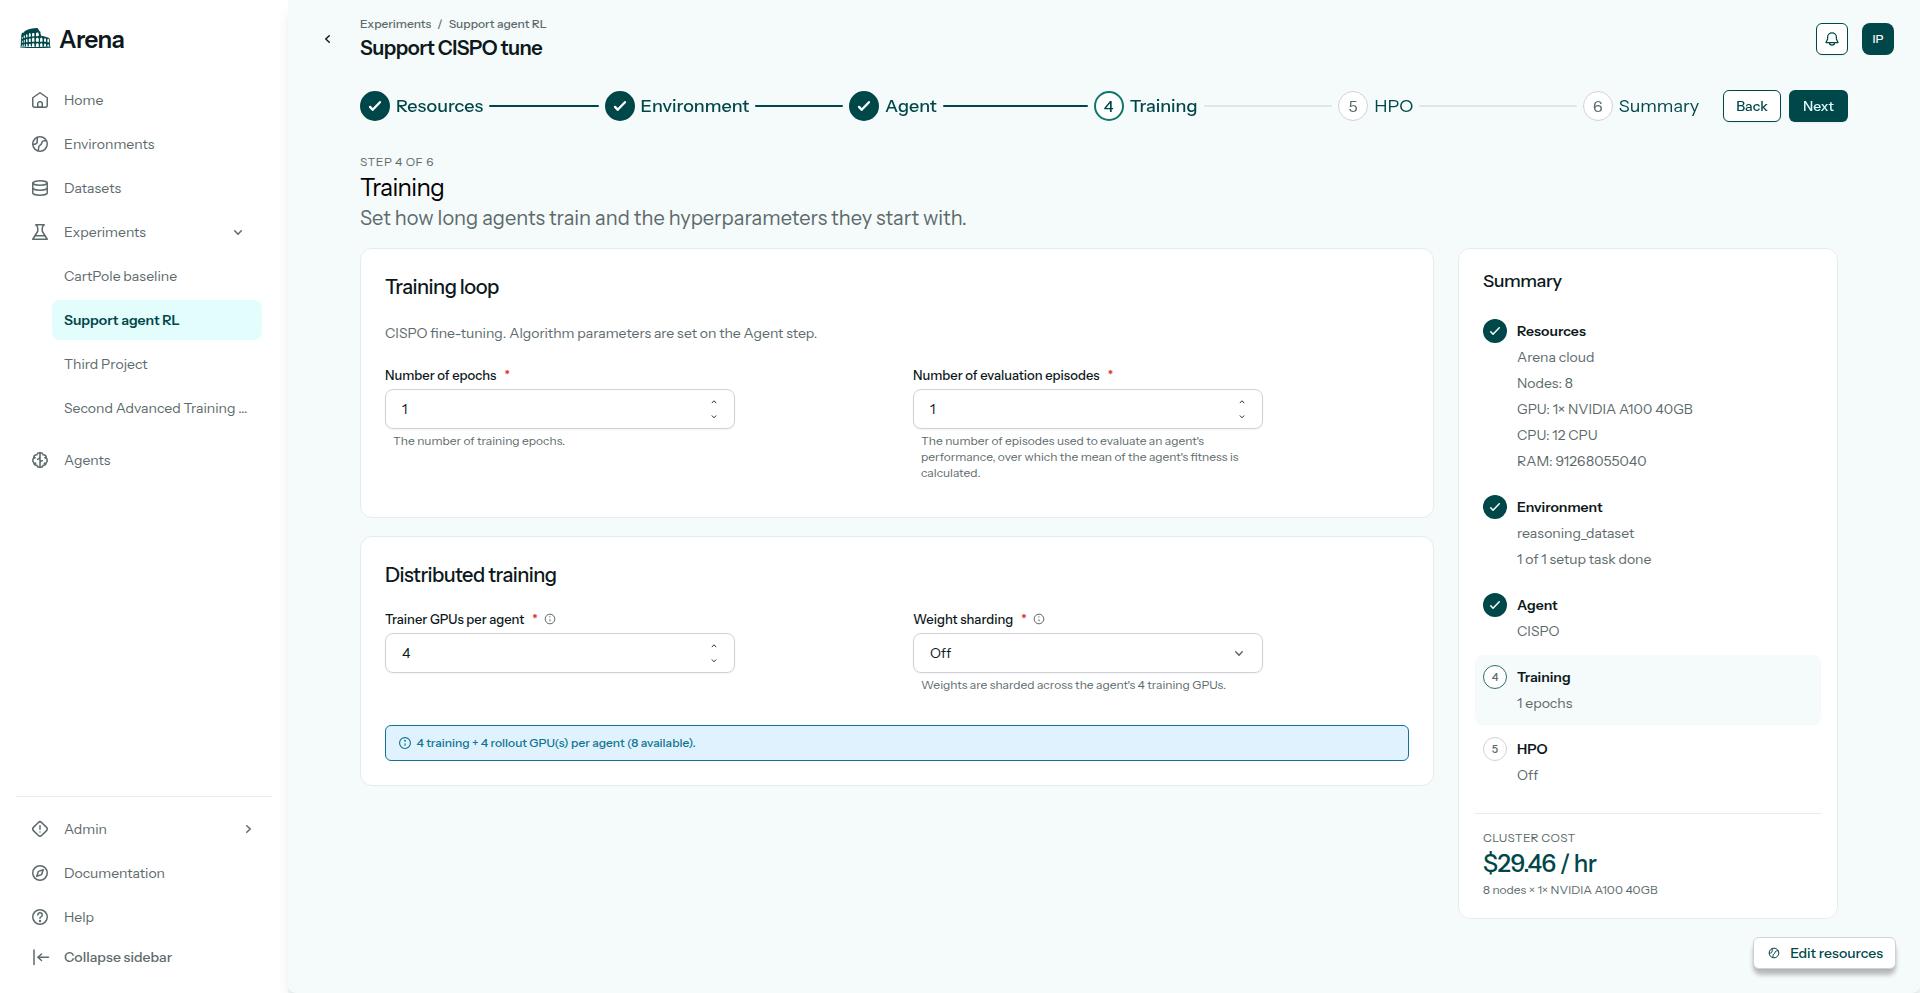
The Training step.
8. Summary
Review the configuration on Summary.
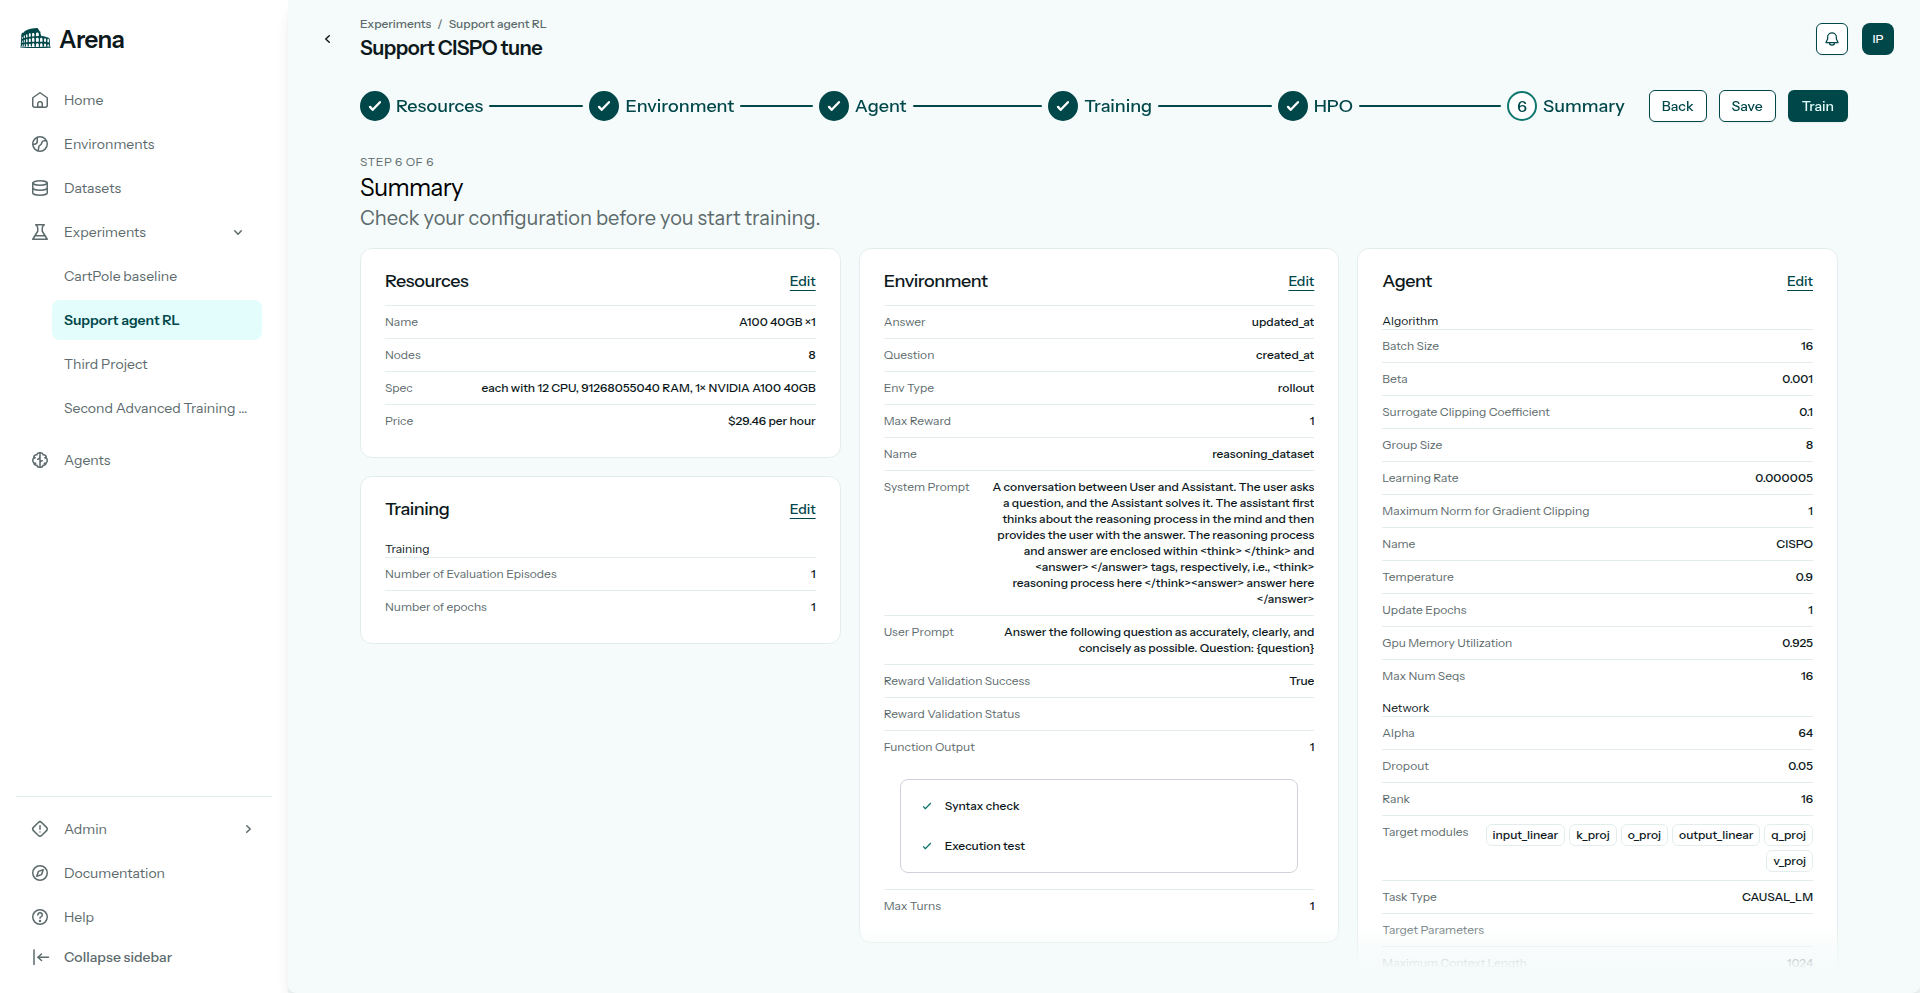
Summary before starting the run.
9. Running experiment
Click Train. The experiment row shows status while the job runs.
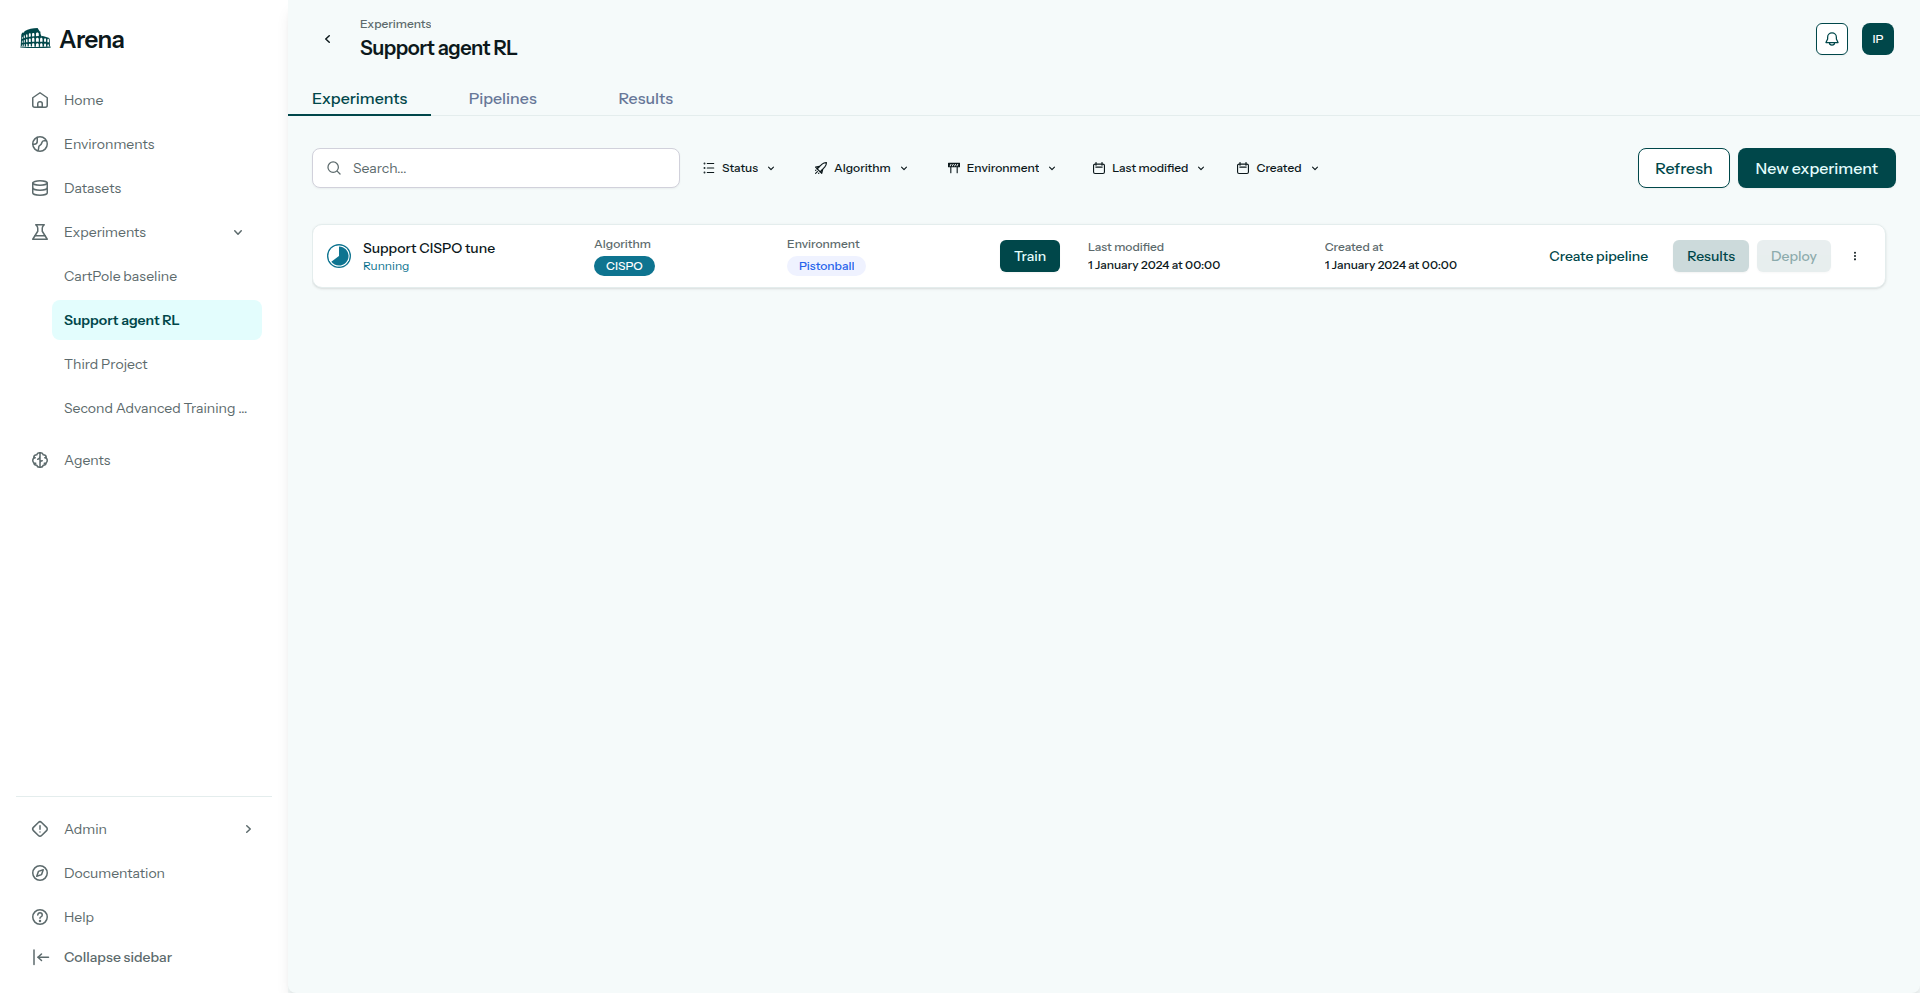
An experiment with an active training status.
From the terminal
Save a default spec from Python as cispo-run-spec.json, then submit. Copy a resource id from arena resources list.
Install the CLI and sign in (Authentication):
pip install "agilerl[arena]"
arena login
# or: export ARENA_API_KEY=arena_pat_…
import json
from pathlib import Path

from agilerl.arena import ArenaClient

with ArenaClient() as client:
    spec = client.get_default_run_spec(
        algorithm="CISPO",
        dataset_name="math-word-problems",
    )
    Path("cispo-run-spec.json").write_text(json.dumps(spec, indent=2))
arena resources list

arena experiments submit ./cispo-run-spec.json --project llm-work --experiment-name cispo-run --resource-id a2-highgpu-1g --num-nodes 2 --reward-file ./reward.py
reward.py should define def reward_function(question, answer, completion) and return a float.
Python
from agilerl.arena import ArenaClient

with ArenaClient() as client:
    spec = client.get_default_run_spec(
        algorithm="CISPO",
        dataset_name="math-word-problems",
    )
    client.submit_experiment(
        manifest=spec,
        project="llm-work",
        resource_id="a2-highgpu-1g",
        experiment_name="cispo-run",
        num_nodes=2,
        reward_file="./reward.py",
    )
    print(client.list_experiments(project="llm-work"))